Programming, Python
Statistics for Data Science: Complete Guide with Examples
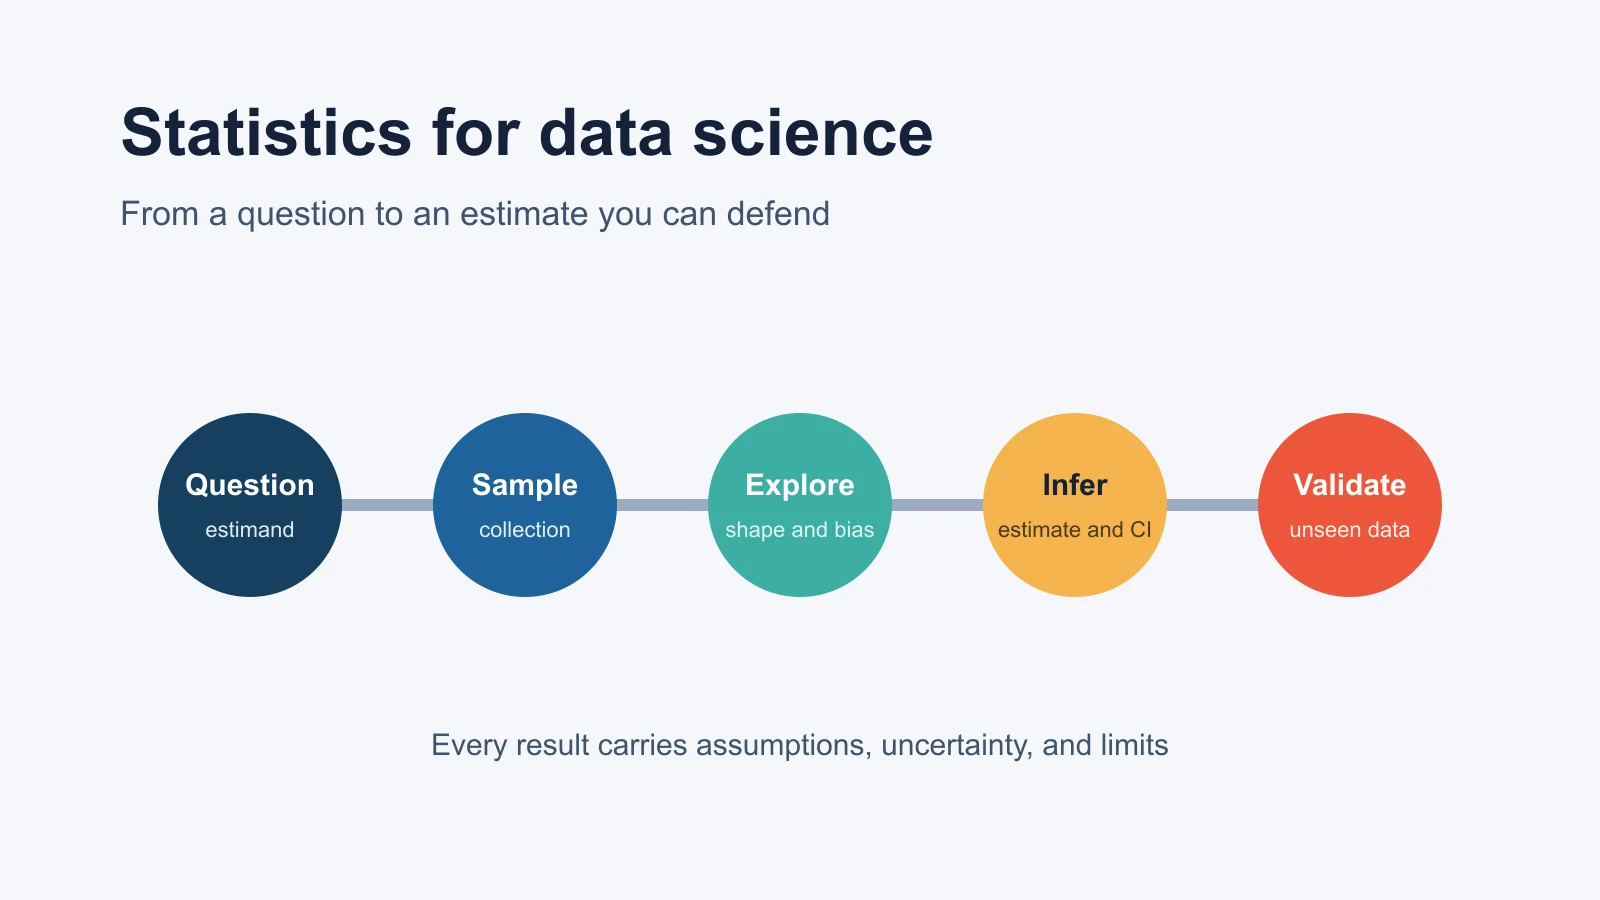
Underneath its code, algorithms, and dashboards sits statistics: the part that separates a repeatable signal from random variation. This guide starts with the fundamentals, then works through sampling, distributions, hypothesis tests, regression, visualization, and model validation with Python examples.
What does statistics contribute to data science?
Statistics converts observed data into estimates, decisions, and predictions whose uncertainty can be measured. A dashboard can report what happened, but statistical reasoning asks whether the pattern is stable, whether the sample represents the population, and how much error surrounds the result.
Three questions organize most data science work:
- What does this dataset contain? Descriptive statistics summarize its center, spread, shape, and missingness.
- What can this sample tell us about a population? Inferential statistics attaches uncertainty to estimates and tests.
- How well does a pattern generalize? Statistical learning evaluates a model on observations that did not influence training.
The NIST definition of exploratory data analysis emphasizes graphical inspection, outlier detection, assumption checks, and model discovery. That order matters. Fitting a model before examining the data often hides the exact problem that later invalidates it.
Start with populations, samples, variables, and estimands
Before calculating a mean, name the population, sample, variables, and estimand. These four entities prevent a notebook from drifting away from the question it is meant to answer.
- The population is the complete group of interest, such as all students enrolled in an online course this semester.
- The sample is the observed subset, such as 800 students who opened a voluntary survey.
- A variable is a measured attribute, such as completion time, final score, or subscription status.
- The estimand is the population quantity the analysis seeks, such as the difference in completion rates between two onboarding designs.
A large sample does not repair biased collection. Eight hundred voluntary responses can estimate the opinions of respondents precisely while misrepresenting students who ignored the survey. Sampling bias concerns who entered the data; sampling error concerns the variation produced by observing only part of the population.
Match the summary to the measurement scale
Start by classifying the variable as categorical or numerical. Nominal categories such as operating system have no meaningful order. Ordinal values such as satisfaction ratings have an order but uncertain spacing. Interval and ratio variables support arithmetic differences, while ratio variables also have a meaningful zero.
| Variable | Type | Useful summaries | Common mistake |
|---|---|---|---|
| Programming language | Nominal | Counts, proportions, mode | Calculating an average category code |
| Satisfaction from 1 to 5 | Ordinal | Median, proportions, ordered plot | Treating every step as equally spaced without justification |
| Response time in milliseconds | Ratio | Median, quantiles, mean, standard deviation | Reporting only the mean for a skewed distribution |
| Converted or not converted | Binary | Proportion, odds, risk difference | Ignoring the denominator |
Describe the distribution before choosing a model
A useful numerical summary reports center, spread, shape, and unusual observations together. A single average removes information about skew, multiple clusters, and outliers.
Consider eight task-completion times in minutes:
from statistics import mean, median, stdev

minutes = [8, 10, 12, 13, 15, 16, 18, 120]

print(f"mean: {mean(minutes):.1f}")
print(f"median: {median(minutes):.1f}")
print(f"sample standard deviation: {stdev(minutes):.1f}")
mean: 26.5
median: 14.0
sample standard deviation: 37.9The 120-minute observation pulls the mean 12.5 minutes above the median and inflates the standard deviation. Neither value is wrong. The median answers what a typical ordered observation looks like, while the mean represents the arithmetic balance point. Reporting both reveals the skew that either statistic alone would conceal.
Use variance, standard deviation, and quantiles for different jobs
Measures of dispersion describe how widely the observations vary. Choose one whose units and sensitivity match the task. Variance averages squared deviations and appears throughout statistical theory, but its squared units make it awkward to explain. Standard deviation returns to the original units but remains sensitive to outliers. The interquartile range covers the middle 50 percent and resists extreme observations.
For a sample of size n, the sample variance is:
s² = Σ (xᵢ - x̄)² / (n - 1)
where Σ sums over i = 1 … n
The denominator is n - 1 because one degree of freedom was used to estimate the sample mean. Python libraries distinguish sample variance from population variance through parameters such as ddof.
Read histograms and box plots as diagnostic tools
Pair numerical summaries with a histogram, box plot, or empirical cumulative distribution to inspect the shape. A histogram makes skew and multiple peaks visible, but its appearance changes with bin width. A box plot compresses the median, quartiles, and potential outliers, but it can hide multiple clusters.
Plots do not decorate an analysis. They expose assumptions that a summary table cannot show.
Use probability distributions as models, not labels
Probability distributions become useful when their assumptions match the process that generated the observations. A distribution is a mathematical model for outcomes, not a badge applied because a plot looks roughly familiar.
| Distribution | Models | Key conditions | Data science example |
|---|---|---|---|
| Bernoulli | One binary trial | Two outcomes with probability p | One visitor converts or does not convert |
| Binomial | Count of successes in n trials | Fixed n, stable p, independent trials | Conversions among 1,000 visitors |
| Poisson | Event count in an interval | Independent events at a stable average rate | Support tickets arriving in one hour |
| Normal | Continuous values around a mean | Symmetric shape; many small influences | Measurement error under controlled conditions |
Real data often violates the convenient version of these conditions. Repeated activity from the same user is not independent. Ticket arrivals change by time of day. Revenue has a hard lower bound and a long right tail. The appropriate model depends on those facts.
Quantify uncertainty with confidence intervals
Give every estimated effect a confidence interval alongside its point estimate. A 95 percent confidence procedure is designed so that, across repeated samples generated under the model, 95 percent of the resulting intervals contain the true parameter.
That definition does not mean there is a 95 percent probability that a fixed population parameter lies inside one already calculated frequentist interval. The parameter is fixed; the interval-producing procedure has the long-run coverage rate. The NIST confidence-interval guidance also notes that estimating variability from limited data widens an interval.
Suppose an A/B test records 82 conversions among 1,000 control visits and 104 among 1,000 variant visits. The estimated lift is 2.2 percentage points, but the approximate 95 percent confidence interval for that difference runs from -0.34 to 4.74 percentage points.
from math import sqrt

control_successes, control_n = 82, 1000
variant_successes, variant_n = 104, 1000

p_control = control_successes / control_n
p_variant = variant_successes / variant_n
difference = p_variant - p_control

standard_error = sqrt(
    p_control * (1 - p_control) / control_n
    + p_variant * (1 - p_variant) / variant_n
)

lower = difference - 1.96 * standard_error
upper = difference + 1.96 * standard_error

print(f"difference: {difference:.3%}")
print(f"95% CI: [{lower:.3%}, {upper:.3%}]")
difference: 2.200%
95% CI: [-0.344%, 4.744%]The data remains compatible with a small loss, no effect, or a commercially useful gain. That range is more informative than declaring that the variant “worked” because its observed conversion rate was larger.
Test hypotheses without turning p-values into verdicts
A hypothesis test starts with the null hypothesis, alternative hypothesis, test statistic, significance level, and decision rule. Define them before inspecting the result. A p-value measures how incompatible the observed statistic, or something more extreme, is with the null model under its assumptions.
A p-value is not:
- the probability that the null hypothesis is true;
- the probability that the result occurred by chance;
- the size or importance of an effect;
- proof that a result replicates.
For the conversion example, a two-sided z-test gives approximately z = 1.69 and p = 0.09. At a preselected 0.05 significance level, the test does not reject equal conversion rates. “Fail to reject” is the correct conclusion. It does not prove that the two versions are identical.
Keep Type I error, Type II error, and power connected
Planning a useful test means balancing false positives, false negatives, minimum meaningful effect, and sample size. A Type I error rejects a true null hypothesis. A Type II error fails to reject a false null hypothesis. Statistical power is the probability of detecting a specified effect when that effect exists.
Choosing a sample size after seeing whether the result is significant breaks the planned error rates. Power analysis belongs before data collection and needs an effect size worth acting on, not merely the smallest detectable difference a large dataset can produce.
Select statistical tests from the design
The outcome type, group relationship, sampling design, and assumptions determine the test. The familiar test name comes last.
| Question | Typical method | Check before use |
|---|---|---|
| Does one numerical sample differ from a reference mean? | One-sample t-test | Independence and behavior of the sampling distribution |
| Do two independent groups differ in mean? | Welch’s t-test | Independent groups; inspect skew and outliers |
| Did the same subjects change after an intervention? | Paired t-test | Pairing retained; analyze within-pair differences |
| Are two categorical variables associated? | Chi-square test | Expected cell counts and independent observations |
| Do 3 or more independent groups differ in mean? | ANOVA | Independence, residual behavior, variance assumptions |
| How does a continuous outcome change with predictors? | Linear regression | Functional form, residuals, dependence, influential points |
| How does a binary outcome change with predictors? | Logistic regression | Independent units, specification, calibration, separation |
Repeated measurements, clustered classrooms, and time series violate the independence assumed by many introductory tests. Mixed-effects models, clustered standard errors, or time-series methods may fit those designs better.
Connect regression to prediction and explanation
Regression can support prediction, description, or causal explanation, but those goals require different evidence. Decide which one the analysis serves before interpreting a coefficient.
A linear regression writes an outcome as:
yᵢ = β₀ + β₁xᵢ₁ + … + βₚxᵢₚ + εᵢThe coefficients describe conditional associations under the fitted specification. They do not become causal effects merely because the model controls for several variables. Causal interpretation also requires a credible design, such as randomization or a defensible identification strategy.
For prediction, evaluate errors on unseen observations and compare against a simple baseline. For explanation, examine uncertainty, residuals, influential observations, and whether omitted variables could distort the association.
Prevent leakage during model evaluation
Separate the test data before learning preprocessing values, selecting features, or tuning hyperparameters. That split estimates generalization. Data leakage occurs when information unavailable at prediction time influences model fitting and produces an optimistic score.
The scikit-learn guidance on data leakage gives a direct rule: split first, then fit preprocessing only on the training subset. A pipeline keeps those operations inside each cross-validation fold.
from sklearn.impute import SimpleImputer
from sklearn.linear_model import LogisticRegression
from sklearn.model_selection import cross_val_score
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler

model = make_pipeline(
    SimpleImputer(strategy="median"),
    StandardScaler(),
    LogisticRegression(max_iter=1000),
)

scores = cross_val_score(model, X, y, cv=5, scoring="roc_auc")
print(scores.mean(), scores.std())
Cross-validation does not fix a bad split. Time-ordered data needs forward-looking validation. Multiple rows from one patient, speaker, household, or device need group-aware splitting. Otherwise the model partly recognizes the entity instead of learning a pattern that transfers to new entities.
Handle missing data as part of the data-generating process
Missing values require an explanation before they require an imputation method. Missing completely at random, missing at random conditional on observed variables, and missing not at random imply different risks.
Median imputation may keep a pipeline running, but it can narrow variance and weaken relationships. A stronger report states the missingness rate by variable, compares observed groups, documents the imputation method, and checks whether conclusions change under reasonable alternatives.
The same reasoning applies to outliers. Correct a recording error when evidence identifies it as an error. Retain a valid extreme observation, use a method that limits outlier influence, or report a sensitivity analysis when the value represents a real case.
Follow a reproducible statistical workflow
A complete data science analysis keeps the question, code, assumptions, and decisions in one reproducible chain.
- Define the population, unit of analysis, outcome, predictors, and estimand.
- Record how observations were sampled and which rows were excluded.
- Profile types, ranges, duplicates, missingness, and impossible values.
- Visualize distributions and relationships before fitting a model.
- Select methods from the design and verify their assumptions.
- Report estimates with uncertainty and practical units.
- Validate predictions on a split that matches future use.
- Run sensitivity checks for missing data, outliers, and alternate specifications.
- Preserve seeds, package versions, and transformation logic.
- Explain what the data does not establish.
Students working through an unfamiliar analysis can use statistics homework help for hypothesis tests and interpretation, Python assignment help for reproducible notebooks, or machine learning assignment help for leakage-safe model evaluation. Each result still needs a plain-language explanation that you can defend.
Questions students ask about statistics for data science
Which statistics topics matter most for data science?
The most useful foundation includes sampling, variable types, distributions, descriptive statistics, confidence intervals, hypothesis tests, regression, experimental design, and model validation. Probability supports all of them by describing uncertainty.
Is statistics required for machine learning?
Statistics is required to understand sampling, bias, loss functions, uncertainty, evaluation, and generalization. A library can fit a model without that knowledge, but it cannot decide whether the score answers the real question.
What is the difference between descriptive and inferential statistics?
Descriptive statistics summarizes the observed dataset. Inferential statistics uses a sample and a probability model to estimate or test claims about a broader population.
Why can the mean and median disagree?
The mean responds strongly to extreme values, while the median depends only on order. A right-skewed variable such as income or completion time often has a mean above its median.
Does a p-value below 0.05 prove an effect?
No. It indicates that the observed statistic is relatively incompatible with the null model at the chosen threshold. Effect size, confidence interval, study design, multiplicity, and replication provide the context for interpretation.
What is the difference between correlation and causation?
Correlation describes an association between variables. Causation requires evidence that changing one variable changes another, supported by the study design and assumptions rather than the correlation coefficient alone.
Why is train-test leakage a statistical problem?
Leakage makes the evaluation sample partly known during training. The resulting metric no longer estimates performance on genuinely unseen data, so its uncertainty and practical meaning are compromised.
When is cross-validation appropriate?
Use cross-validation when data is limited and repeated estimates help compare models or tune settings. Choose folds that respect time, groups, and the future prediction setting; random folds are not valid for every dataset.
References
Related articles
-
 Programming
How to Become a Python Developer
A step-by-step roadmap covering core Python concepts, libraries, frameworks, databases, testing, DevOps, and interview prep for aspiring Python developers.
Oct 26, 2024
-
 Programming
Python Files and Directories Explained
Learn how to work with files and directories in Python using the os and glob modules, covering absolute paths, relative paths, and directory listing.
Feb 27, 2023
-
 Machine Learning
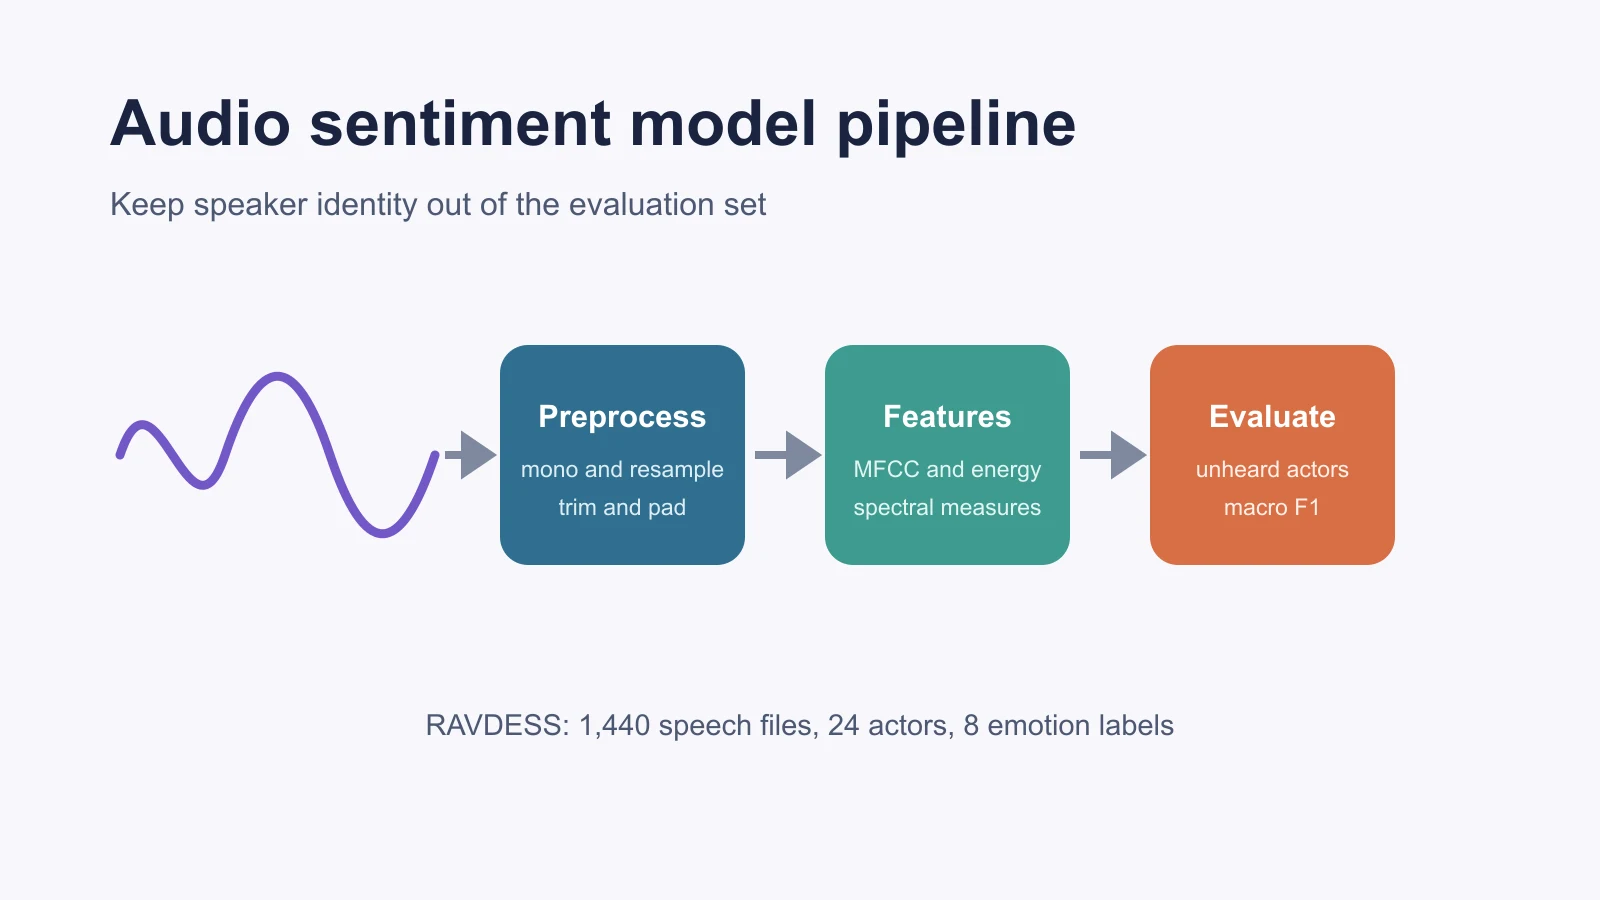
Building a Sentiment Analysis Model With Audio Data
Build and evaluate an audio sentiment model in Python using RAVDESS, librosa features, actor-grouped validation, and honest emotion labels.
Sep 23, 2026